
Understanding the core mechanics of federated learning
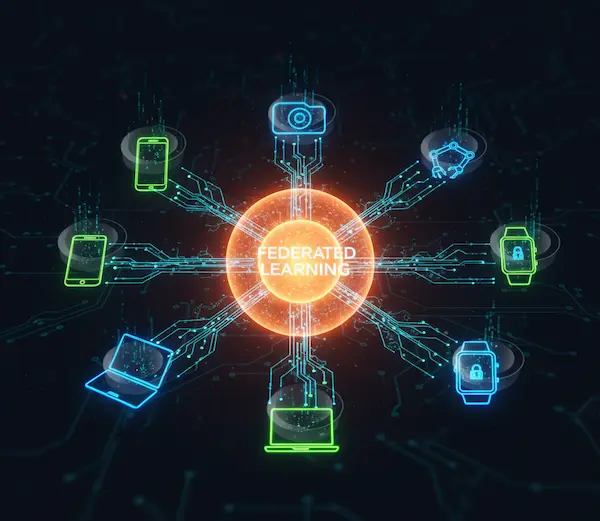
At its essence, federated learning flips the traditional AI training model on its head. Instead of bringing the data to the model in a central location, it brings the model to the data. A central server orchestrates the training process by sending an initial, shared AI model to a multitude of participating devices. Each device then trains a local version of this model using its own, private data. Rather than sending this sensitive local data back to the server, only the learned updates or changes to the model are transmitted. These updates are then aggregated by the central server to improve the global model, ensuring data privacy remains intact on the user's device.
The privacy dilemma in traditional machine learning
Traditional machine learning relies heavily on large, centralized datasets. Companies collect vast amounts of user data – from browsing habits to personal health information – to train powerful AI models. While this approach has led to significant breakthroughs, it inherently creates a major privacy risk. Centralized data stores are vulnerable to breaches, and even anonymized data can sometimes be re-identified. This fundamental conflict between the need for data to train AI and the right to user privacy has become a critical bottleneck, hindering AI adoption in sensitive domains and fueling public skepticism.
How federated learning protects user data
Federated learning addresses this dilemma by ensuring that raw, sensitive user data never leaves the device. When a device trains a local model, it learns patterns specific to its user's data. Only the parameters or weights of the trained model, representing generalized learning, are sent back to the central server. These updates are often encrypted and aggregated with updates from hundreds or thousands of other devices before being applied to the global model. This process offers strong privacy guarantees, as individual data points are never directly exposed to the central server or other participants, significantly reducing the risk of data leakage or re-identification.
The unique advantages of federated learning
Beyond its privacy benefits, federated learning offers several other compelling advantages that make it an attractive solution for developing robust and efficient AI systems. These benefits extend to operational costs, system performance, and the ability to leverage a broader range of data sources that would otherwise be inaccessible due to privacy or logistical constraints. Understanding these advantages highlights why it's a critical technology for future AI deployments.
Enhanced privacy and data security
The most prominent advantage of federated learning is its inherent ability to enhance data security and privacy. By keeping sensitive user data on the local device, it significantly reduces the risk of large-scale data breaches that can occur in centralized systems. This decentralization minimizes the attack surface and helps comply with stringent data protection regulations such as GDPR or HIPAA. For applications dealing with highly sensitive information, such as medical records or financial transactions, federated learning provides a crucial layer of protection, building greater trust with users.
Reduced communication costs and bandwidth usage
Federated learning can lead to significant reductions in communication costs and network bandwidth usage. Instead of constantly streaming raw data from numerous devices to a central cloud, only smaller model updates are transmitted. This is particularly beneficial for devices with limited connectivity or in environments where sending vast amounts of data is expensive or impractical. For example, a smartphone might train a language model using local text data, sending only a few megabytes of model updates, rather than gigabytes of personal communication logs, thereby optimizing network resources.
Access to diverse and real-world data
Federated learning allows AI models to be trained on a vastly more diverse and representative range of real-world data than might be available in a single, centralized repository. Each participating device contributes its unique data patterns, leading to a more robust and generalized global model. This access to data from the "edge" enables AI to learn from actual user behavior and varied environmental conditions, improving its adaptability and performance in diverse scenarios. This ensures the model is not biased by a narrow dataset and instead reflects a broader spectrum of user interactions.
Improved robustness and generalization of models
Training models on decentralized, heterogeneous datasets also contributes to improved model robustness and generalization. By learning from the unique characteristics of data across many different devices and user contexts, the global model becomes less susceptible to overfitting on a specific dataset. It develops a greater ability to perform well on new, unseen data, enhancing its practical applicability. This distributed learning makes the AI more resilient to variations in data distribution and more adaptable to real-world complexities.
Key applications and real-world implementations
Federated learning is already moving beyond academic research into practical applications, solving real-world problems in various sectors. Its ability to reconcile AI development with privacy concerns makes it particularly valuable for industries dealing with sensitive data or requiring on-device intelligence. Examining these use cases provides concrete examples of the transformative impact of this privacy-preserving AI paradigm.
Smart mobile devices and predictive typing
Perhaps the most common real-world application of federated learning is in smart mobile devices. Google's Gboard keyboard, for instance, uses federated learning to improve its predictive typing and next-word suggestions. The AI model learns from how you type on your phone, suggesting more accurate words over time, without ever sending your private messages or keystrokes to Google's servers. Only the aggregated model improvements are shared, ensuring your personal communications remain private while the AI continually gets smarter for all users, offering a truly personal experience.
Healthcare and medical research
The healthcare sector stands to benefit immensely from federated learning, particularly given the extreme sensitivity of patient data. Hospitals and research institutions can collaboratively train AI models for disease detection, drug discovery, or personalized treatment plans using their localized patient data, without ever pooling or directly sharing individual records. This enables the development of powerful medical AI that learns from a vast, diverse patient population while strictly adhering to privacy regulations like HIPAA and maintaining data confidentiality. It facilitates breakthroughs that would otherwise be impossible due to data siloing.
Financial services and fraud detection
In the financial sector, federated learning can enhance fraud detection and risk assessment. Banks and financial institutions can collaboratively train AI models to identify new fraud patterns by leveraging their individual datasets, without exposing sensitive customer transaction details to competitors or a central server. This enables more robust and adaptive fraud detection systems that learn from a wider range of fraudulent activities globally, improving the accuracy of identification while ensuring that customer financial data remains strictly confidential within each institution's control, strengthening the overall security of financial transactions.
IoT and edge devices
Federated learning is a natural fit for IoT and edge devices, which often generate vast amounts of data locally but have limited bandwidth or privacy constraints for transmitting raw data. Smart home devices can learn user preferences or optimize energy consumption patterns. Industrial sensors can collectively improve predictive maintenance models. Autonomous vehicles can learn from diverse driving conditions across multiple cars. In all these scenarios, federated learning allows AI to enhance device intelligence by leveraging local data without compromising user privacy or overloading networks, making smart environments truly intelligent.
Autonomous driving and shared learning
Autonomous vehicles present another compelling use case for federated learning. Each self-driving car collects enormous amounts of data from its sensors about road conditions, traffic, and unexpected events. Federated learning allows these vehicles to collaboratively improve their AI models for perception, prediction, and control. Cars can share their learned experiences – such as identifying a new type of obstacle or navigating a complex intersection – to enhance the global AI model, without transmitting sensitive data about individual journeys. This enables a rapid, collective improvement of the autonomous driving system, leading to safer and more efficient self-driving capabilities for all vehicles in the fleet.
Challenges and future directions in federated learning
While federated learning presents a powerful solution, it is not without its challenges. Overcoming these obstacles is crucial for its widespread adoption and for unlocking its full potential. Researchers and practitioners are actively working on refining algorithms, improving security, and developing better deployment strategies. Addressing these challenges will pave the way for a new era of privacy-preserving AI that balances utility with ethical considerations.
Algorithmic and optimization challenges
One of the key challenges lies in the algorithmic optimization of federated learning. The decentralized and often heterogeneous nature of data on edge devices can make training more complex than with centralized data. Devices may have vastly different data distributions, network connectivity, and computational capabilities. Developing robust aggregation algorithms that can effectively synthesize diverse local updates into a coherent global model, while accounting for varying device availability and data quality, remains an active area of research to ensure consistent model performance.
Security and privacy enhancements
While federated learning offers strong privacy benefits, it is not entirely immune to sophisticated attacks. Researchers are exploring ways to enhance privacy further through techniques like differential privacy, which adds calibrated noise to model updates to obscure individual contributions, making re-identification even harder. Additionally, secure multi-party computation (SMC) and homomorphic encryption are being investigated to allow for encrypted aggregation of model updates, preventing the central server from even seeing individual gradients, thus providing an even stronger layer of cryptographic protection against malicious central servers or external attackers.
System heterogeneity and device management
Managing the system heterogeneity of participating devices is another significant hurdle. Devices can vary wildly in terms of processing power, battery life, memory, and network speed. This variability can affect the speed and reliability of local model training and update transmission. Developing robust orchestration frameworks that can intelligently select participating devices, manage their contributions, and adapt to varying conditions is essential for efficient and scalable federated learning deployments. Effective device management ensures that the training process is stable and makes optimal use of available resources without overburdening individual devices.
Regulatory and ethical considerations
As federated learning gains traction, it brings forth important regulatory and ethical considerations. While it addresses many privacy concerns, questions remain about data ownership, consent mechanisms, and accountability when AI models are trained on distributed, private datasets. Defining clear guidelines for data governance, ensuring transparency in model aggregation, and establishing mechanisms for user control over their contribution to the global model are critical for building trust and ensuring that federated learning is deployed responsibly and in accordance with evolving data protection laws worldwide.


