
Editorial correction, 27 October 2026. An earlier version described a first-person incident with a $47,000 monthly loss and a fixed recovery timeline. We do not have verifiable records supporting that account, so the anecdote and reported outcomes have been removed. The figures used below are explicitly hypothetical and demonstrate why the original revenue calculation was insufficient.
A working page can still be blocked for a crawler
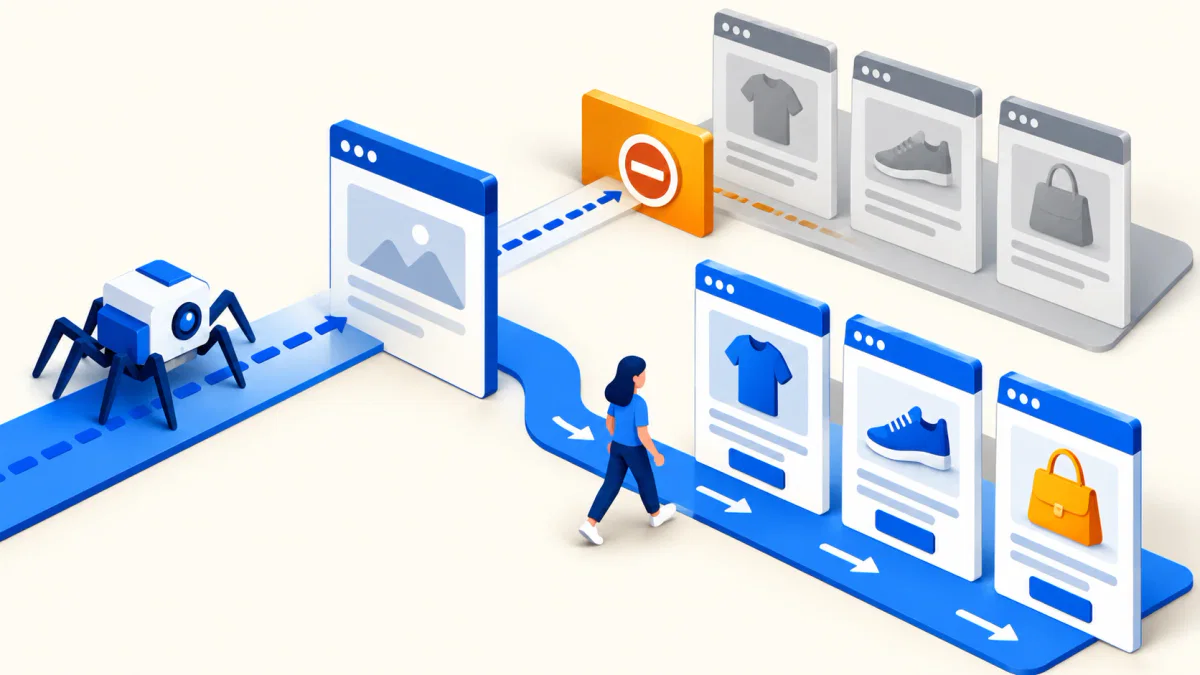
A browser request returning HTTP 200 establishes that the server delivered a response to that request. It does not establish that Googlebot is allowed to fetch the page under the applicable robots.txt rules. Those are separate checks. The robots.txt specification used by Google explains how crawler groups and matching paths are evaluated.
User-agent: *
Disallow: /products/
Disallow: /categories/
Disallow: /blog/
In this simplified example, with no more-specific Googlebot group or competing rules, a compliant crawler is asked not to fetch URLs under those three paths. The rule does not prevent a customer from visiting a product page. A crawler configured to respect robots.txt may record the URL as blocked without fetching its body. A separate browser or a crawl run that ignores those rules can therefore produce a different result.
Check the full file rather than isolating one line. A more-specific crawler group or a more-specific Allow rule may change the result for a particular URL. Keep the protocol, hostname and port in scope: a file on a staging subdomain does not automatically control production. A folder such as /test-products/ is a path, not a subdomain.
Build the diagnosis from representative URLs
- Select several affected URLs and a comparable unaffected section. Include important product or category pages and examples with different path patterns. Record the last normal date and the first observed decline without assuming that the robots.txt change happened at exactly that moment.
- Fetch the production robots.txt and save its text, response status and retrieval time. Check the robots.txt report in Search Console and any deployment history available to establish which rules changed and when.
- Inspect the selected URLs in Search Console. Record the last crawl, crawl permission, page-fetch result, indexing status and canonical information. Compare the indexed report with a live test when checking the current configuration.
- Run a crawl with the relevant user-agent and robots.txt handling explicitly recorded. Examine the blocked-URL results; if a second diagnostic crawl ignores robots.txt, label it accordingly rather than treating the two runs as the same test.
- Check competing explanations for the traffic loss: a noindex directive, changed canonicals, redirects, server failures, missing internal links, analytics-tag changes or a shift in demand. Keep evidence for each explanation separately.
Search Console can report crawl restrictions and indexing problems; the earlier claim that it would not catch a robots.txt block was unjustified. Its URL Inspection documentation also distinguishes the indexed report from a live test. A live fetch result helps assess the current page, but it does not establish that Google has reindexed it or restored its rankings.
A “Not Found” value in a crawl-depth field is not, by itself, a diagnosis. Depth depends on how a crawler discovered a URL, including its start points and integrations. Preserve the crawl configuration and use the actual robots restriction, page-fetch and indexing evidence to explain the problem.
Correct the narrow rule that conflicts with the intended access
If the production file accidentally contains Disallow: /products/ and those products should be crawlable, remove or adjust that unintended rule while preserving deliberate restrictions. Do not replace the whole file with an unrestricted template without reviewing what it protects from crawling. Retest representative URLs, including exceptions, after the change.
Google normally caches robots.txt, and fetching a new version can take time. After updating the production file, use the robots.txt report’s recrawl function if a faster refresh is needed. Repeatedly reloading the file in your own browser does not show that Google’s cached copy has changed.
A robots.txt block controls crawling rather than guaranteeing removal from search. A linked URL can still appear without its content being fetched. Conversely, Google must be allowed to fetch a page to see its noindex instruction. Blocking the page and adding noindex can therefore work against the intended result. Robots.txt also does not secure private data; that requires appropriate access controls.
Keep the file response itself separate from a disallowed page. Our explanation of robots.txt HTTP 403 responses covers a different failure mode. For JavaScript-dependent indexing directives, the initial-HTML noindex problem needs its own diagnosis rather than an unrelated robots.txt edit.
Estimate revenue at risk without inventing a loss
A site owner needs both a defensible baseline and evidence that the blocked section caused the change. Compare like-for-like periods, check analytics collection and consent changes, and separate organic landing pages in the affected paths from unaffected paths. Review completed purchases or the appropriate conversion measure rather than assigning the entire business decline to one technical fault.
Hypothetical inputs. Imagine a baseline of 185,000 organic sessions and $79,000 in purchase revenue over a comparable period, followed by 47,000 sessions. Assume, only for this scenario, that revenue per session is unchanged and every missing session is attributable to the block.
- Baseline revenue per session = $79,000 ÷ 185,000 = approximately $0.4270.
- Missing sessions = 185,000 − 47,000 = 138,000.
- Scenario revenue at risk = 138,000 × ($79,000 ÷ 185,000) = approximately $58,930.
Those inputs do not yield $47,000. They also do not prove an actual $58,930 loss. Revenue per session can change with device mix, customer intent, product availability, prices, repeat purchases and attribution. Some sales might shift to other channels. The calculation is a conditional exposure estimate, not a verified client result or a profit figure.
For a usable business report, show the affected landing-page group, comparison dates, observed orders and revenue, any tracking changes, and the assumptions used to estimate what would otherwise have happened. Label the estimate as an estimate. If the available records cannot support attribution to robots.txt, report that limit rather than assigning a precise amount to the incident.
Verify discovery, indexing and traffic as separate outcomes
After repairing an unintended block, verify that the intended URLs are accessible and indexable, the sitemap contains the correct canonical URLs, and internal links can lead to them. A sitemap submission is a discovery signal. An accepted indexing request means the request was received; it does not establish inclusion or ranking recovery.
Google says recrawling can take days to weeks and is not guaranteed to produce inclusion. Track when Google next fetches the affected URLs, whether the reported restriction clears, whether eligible pages are indexed, and whether relevant impressions, clicks and conversions return. A fixed promise of 52% recovery in one month or 97% in three months cannot be made from this example.
Search Console can show the queries and pages visible for your own site, subject to reporting limits. Our guide to Google ranking API options explains that scope. Use comparable periods and traffic sources rather than treating a handful of returning keywords as proof that the business has recovered.
Prevent the same publishing mistake
Include the production robots.txt in deployment review, compare the outgoing file with the approved version, and keep a rollback copy. Add automated checks for representative public URLs that should remain allowed and private or intentionally excluded paths that should remain restricted. Alert on unexpected response codes as well as content changes.
Choose monitoring and ownership the team can actually maintain. Test that an alert reaches the responsible person and record who can approve a correction. There is no universal two-hour setup cost or five-minute response guarantee. The useful outcome is a verified release check and a measured incident record, with the technical repair and its business consequences documented independently.


