

Publishing economics · SEO
The price of saying yes depends on the cost of saying no
Evaluate the relationship behind an AI content offer before treating visibility as the reward.
- Refusal needs a viable alternativeAn AI-use restriction has more negotiating value when the publisher can preserve other routes to readers.
- The paid event must be explicitFetching a page, using it in an answer and sending a human visitor are different transactions.
- Reporting is part of the bargainA price is hard to evaluate when the buyer also controls the evidence of use.
A publisher is offered a place inside an AI answer. The platform describes it as distribution; the publisher sees reporting, editing and specialist knowledge being turned into someone else’s product. Both descriptions can be true. The disagreement begins when nobody has agreed what the contribution is worth, or what happens if the publisher declines.
The emerging content market is often discussed as a question of payment: will AI companies finally pay for what they use? An earlier question determines much of the answer. Can the supplier refuse a particular use without sacrificing an audience relationship it still needs? If refusing one product also weakens access to another, a nominally voluntary offer can carry a substantial hidden cost.
Three developments make that question concrete: the UK competition regulator’s publisher requirements for Google, Cloudflare’s experiments with charging for access and use, and Microsoft’s Publisher Content Marketplace. They address different parts of the relationship. Read together, they suggest that publishers need a credible alternative, a defined transaction and evidence that lets them judge the result.
The UK is trying to make refusal less expensive
The CMA’s conduct requirement imposed on Google on 3 June 2026 joins two ideas that are easy to discuss separately: controls over AI use and protection against retaliation elsewhere in Search. It requires controls covering training and grounding, including directory- and page-level controls for grounding in Search AI. Grounding means using source material to formulate or check an answer, rather than changing a model through training.
The same notice bars Google from penalising publishers for using those controls by disadvantaging their content in general search outside generative AI features. Its controls, transparency and attribution obligations concern outputs shown to people or organisations located in the UK. This is a specific regulatory intervention, not a worldwide assurance about every AI service.
The CMA’s August implementation summary gives Google until 3 December 2026 to comply, with another three months for the page-level control. As of 12 September, those deadlines are still ahead. The regulator also says parts of the controls and enhanced transparency are already rolling out. Neither “everything is available” nor “nothing changes until December” is a sound reading.
The commercial importance lies in separating two decisions. A publisher may want people to discover an investigation while declining permission for a particular generated answer to stand in for reading it. Preserving that distinction makes refusal more credible. It does not compel the platform to buy the investigation, but it reduces the scope for making acceptance of one use the price of access to another.
There is an equally important limit. The CMA’s interpretative notes acknowledge second-order effects on ranking and explicitly allow negotiations over a publisher’s use of the controls. Protection against deliberate punishment is not a promise of constant visits. Readers can change how they search, and opting out of an AI feature can remove exposure within that feature. A publisher still has to evaluate the audience it gains and loses.
Our separate analysis of Google’s publishing controls deals with the implementation distinctions. Here the question is what an effective control makes negotiable. The presence of a setting alone cannot tell an editor whether using it is commercially sensible.
The unit of payment changes the incentives
Cloudflare’s Pay Per Crawl documentation, updated in July 2026 still describes a closed beta. A participating crawler can present payment intent for access or receive an HTTP 402 response carrying pricing. Cloudflare acts as merchant of record. The documentation also makes an operational limit clear: a separate WAF or Bot Management block overrides the charging feature.
That model attaches a possible price to retrieval. It does not, by itself, price every later answer generated from the retrieved material. Imagine a stable specialist reference page fetched once and consulted repeatedly from a permitted stored copy. The economics depend on the accompanying terms: a low number of new requests could coexist with high downstream usefulness. This is a hypothetical distinction, not a finding about a named crawler’s behaviour.
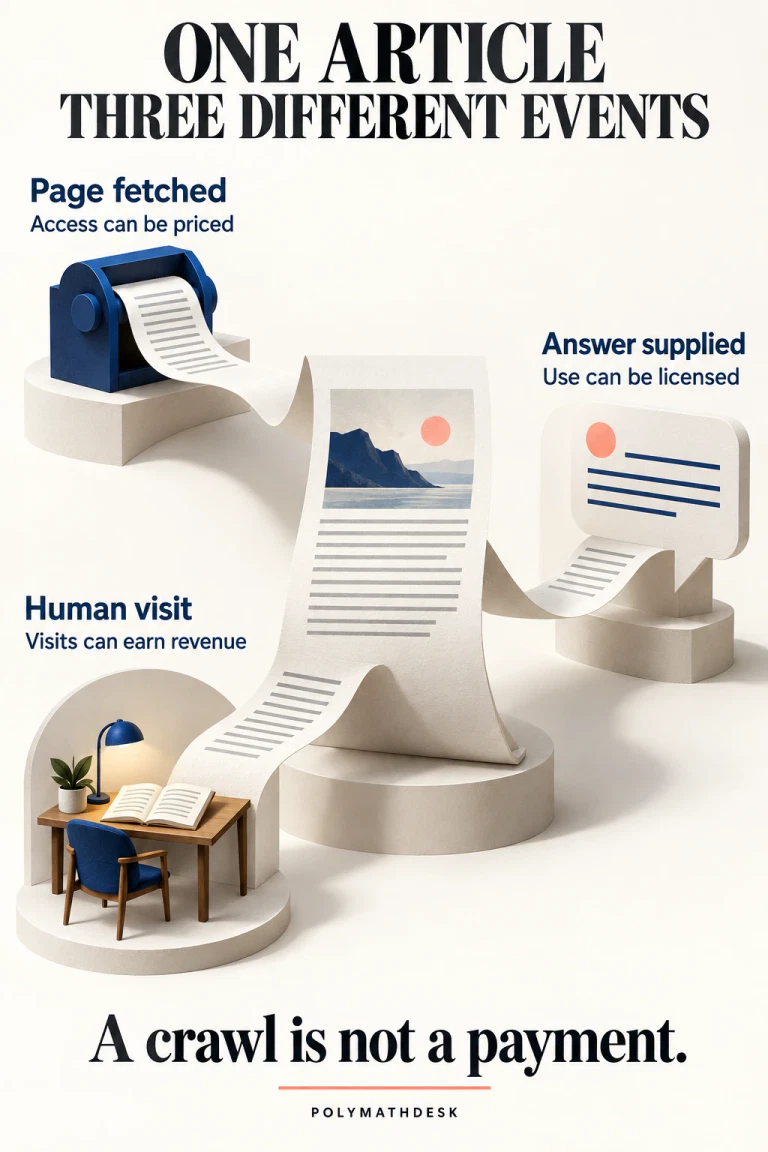
Cloudflare’s 1 July announcement describes a move towards Pay Per Use. Under the announced Ceramic.ai model, opted-in publishers would be paid when their material appears in its AI search results and receive query, citation and ranking information. The announcement describes a different route with You.com: an agent paying on demand for a particular piece of premium content. These are attributed partner models, not evidence that all crawlers now pay or that ordinary publishers have achieved a given return.
Use-based compensation can better follow a source’s contribution, but it also moves the measurement problem. Someone must define a qualifying use, decide how several sources share credit and record the event. If a contract pays for appearances, an appearance becomes economically consequential. If it pays for retrieval, retrieval does. A dashboard showing rising activity says little until its unit matches the agreement.
This is why server log analysis remains useful without settling the commercial question. A request record can help establish access. It cannot independently reveal every subsequent answer, the reader’s satisfaction or the amount contractually owed. Those require different evidence.
Blocking a mixed-use crawler can weaken the negotiating position
Cloudflare’s announced traffic defaults for 15 September 2026 expose the difficulty of making clean choices in a messy distribution system. For new domains, the announced defaults allow Search while blocking Training and Agent categories on pages displaying ads. Its explanation says multipurpose crawlers are subject to all their classifications, with the most restrictive applicable rule prevailing. Customers can choose different settings.
As of this article’s review date, that change is scheduled, not an observed completed rollout. The relevant lesson is already visible in its design: “allow search, refuse training” depends on whether the system can separate the activities. When it cannot, enforcement may obstruct the route to readers that the publisher wanted to preserve.
There is no contradiction between supporting stronger content rights and refusing to treat a broad block as a negotiating strategy. A closed connection is technically decisive; its commercial effect depends on who needs whom. If the publisher loses valuable distribution while the buyer substitutes another source, the restriction may impose the larger cost on its author. If the material is difficult to replace, the same restriction can create a reason to negotiate.
A marketplace can widen access and concentrate power
Microsoft’s February introduction of Publisher Content Marketplace offers another approach. Publishers define licensing and usage terms; AI builders discover and license material for specific grounding scenarios; usage reporting feeds back into the marketplace. Microsoft described voluntary participation, retained ownership and editorial independence, and a pilot being expanded beyond its initial scenarios and partners. That announcement does not establish universal availability or guaranteed demand.
The attraction is straightforward. A small publication may have useful material without the staff to negotiate and maintain a different integration with every AI builder. A common marketplace can reduce that burden, make a specialised archive easier to find and give a buyer a clearer path to permitted use. Rejecting the intermediary on principle could leave the publisher with fewer feasible customers.
The counterweight is control over the new relationship. If a marketplace determines how buyers discover sources, records what counts as use and supplies the report from which payments are assessed, publishers need to understand the scope for verifying or challenging that report. Retaining copyright and editorial independence does not automatically answer those operational questions. They concern the ability to compare deals and leave, rather than ownership of the underlying work.
Nor does a publisher-defined price establish market power. A buyer can decline. A well-designed marketplace should make that decision easier for both sides; it cannot make every source indispensable. Two hypothetical publications show why the outcome will differ.
A
A specialist archive with costly substitutes
A maintained collection of original local records may save a buyer substantial work. A narrowly scoped licence can be attractive if the collection is reliable, rights are clear and the buyer has a recurring use for it.
B
A widely repeated explanatory article
When many lawful alternatives answer the same question, refusing access may lead the buyer to another source. Better access controls do not remove that substitutability; the publisher needs a distinct contribution or another way to earn from readers.
The evidence should let a publisher change its mind
The most useful offer is therefore one that can be evaluated after the enthusiasm of onboarding has faded. The publisher needs to know which material was covered, which activity generated compensation, what reporting can be inspected and how the arrangement can be narrowed or ended. These are questions for the actual agreement. An announcement promising transparency cannot supply their answers.
The CMA’s reporting expectations illuminate the same issue from another direction. Its interpretative notes call for publisher-specific engagement information separated from non-generative Search, including impressions, clicks and click-through rate. That information can help a publisher compare participation with its audience objectives. It does not turn a correlation in a monthly report into proof that an opt-out caused a change in revenue.
An experiment should leave room for learning. A publisher could evaluate a clearly identified collection and time period before expanding an arrangement, keeping changes in audience behaviour separate from changes in licensing income. Where data or commercial terms do not permit that comparison, uncertainty belongs in the decision rather than being hidden inside a single “AI visibility” score.
A direct reader relationship also has value beyond the payment for one use. Our analysis of Preferred Sources examines one platform-mediated way to encourage return visits. Licensing can coexist with that objective, but a publication should know whether a deal helps people recognise and return to its work, compensates for serving them elsewhere, or does some combination of both.
The strongest case for the new systems is that they make more arrangements possible. The strongest concern is that publishers may exchange an opaque distribution bargain for an opaque licensing bargain. The test is whether the supplier can refuse selectively, understand what was purchased and use the evidence to renegotiate. A larger number beside “citations” will not answer those questions for it.
Primary regulatory and product sources
Sources checked 12 September 2026. Regulatory deadlines, announced product changes and commercial pilots are distinguished from completed implementation and measured outcomes. The archive examples are hypothetical.
- CMA — Google search publisher conduct requirement
- CMA — Publisher CR notice, 3 June 2026
- CMA — Publisher CR implementation summary, 4 August 2026
- CMA — Interpretative notes, 3 June 2026
- Cloudflare — What is Pay Per Crawl?
- Cloudflare — Your Content, Your Rules, 1 July 2026
- Cloudflare — New AI traffic options, 1 July 2026
- Microsoft — Building Toward a Sustainable Content Economy, 3 February 2026


